
RAG & Retrieval (Enterprise)
RAG Optimization 3 · Context Pruning
Remove noise; keep only what matters.
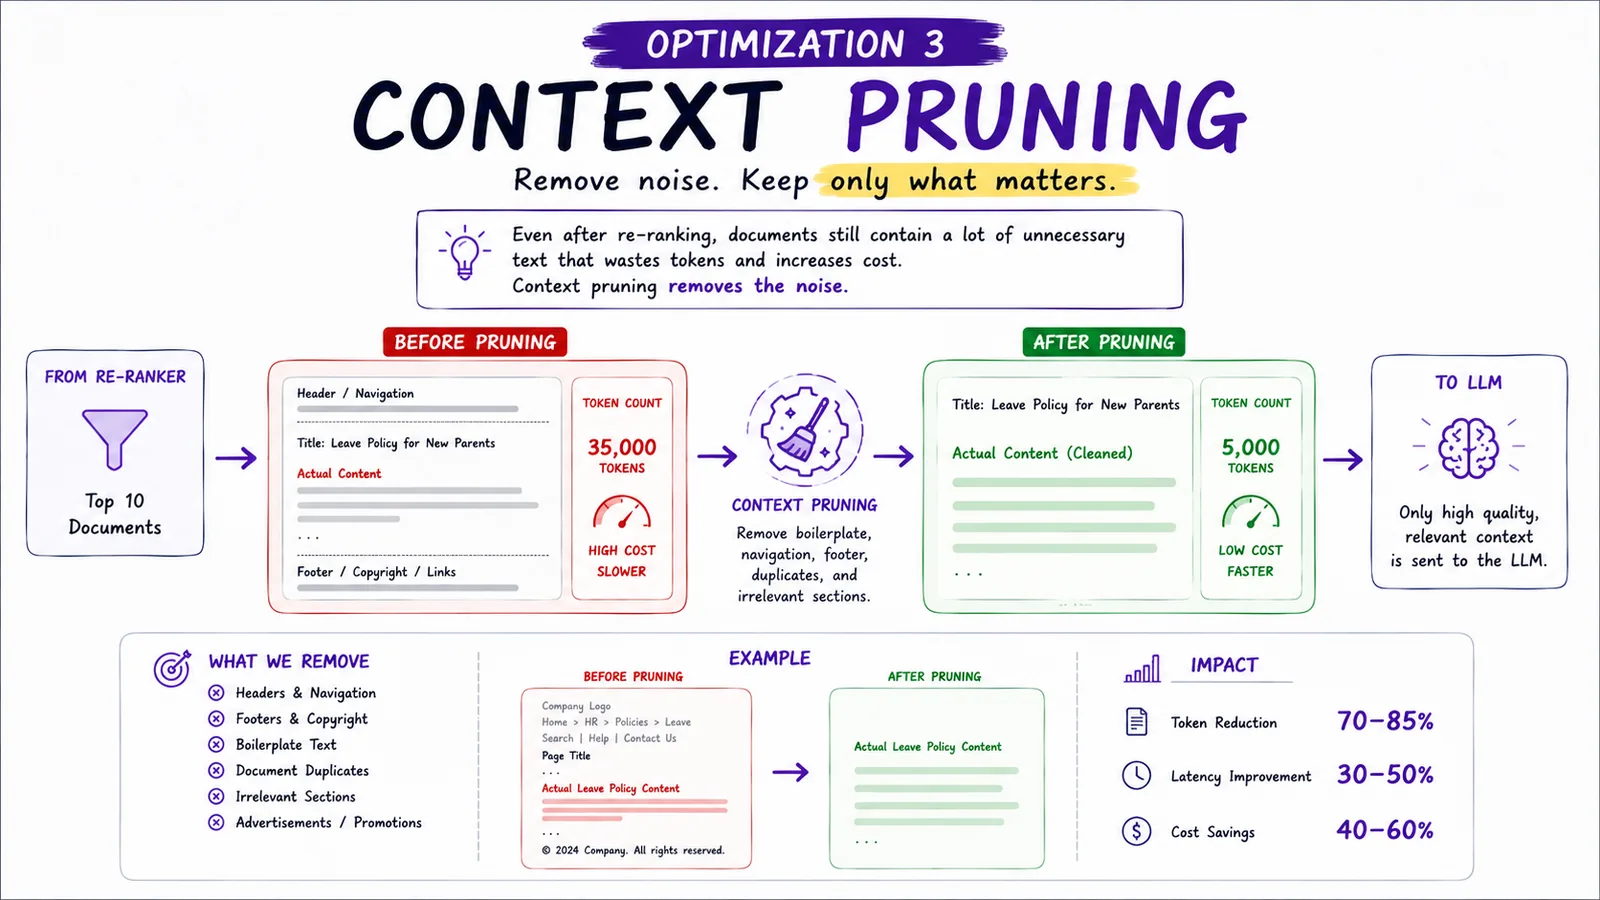
Context pruning removes noise and keeps only what matters. Even after re-ranking, documents contain boilerplate that wastes tokens and increases cost — pruning strips it out.
In simple terms
Remove headers, footers and boilerplate so only the useful content reaches the LLM.
How it works
- 1Start with the top re-ranked documents.
- 2Identify boilerplate: headers, navigation, footers, copyright, duplicates, irrelevant sections.
- 3Context pruning removes that noise.
- 4Keep only the actual, cleaned content.
- 5Send high-quality, relevant context to the LLM.
Key points
- Removes navigation, footers, boilerplate, duplicates and ads.
- Typical impact: 70–85% token reduction, 30–50% latency improvement, 40–60% cost savings.
- Lower cost and faster responses with the same answer quality.
- Cleaner context also reduces the chance of the model being distracted.
Why it matters
Boilerplate silently inflates token usage. Pruning it keeps answers just as good while cutting cost and latency sharply.
Frequently asked questions
- What gets pruned?
- Headers, navigation, footers, copyright text, duplicates and irrelevant sections — noise that wastes tokens.
- Does pruning hurt quality?
- No — it removes noise, not the actual content, so answers stay accurate while cost drops.
More in RAG & Retrieval (Enterprise)
Where Hallucinations Come From
Failures across the query, retrieval and model layers.
RAG Retrieval Optimization Layer
Retrieve the right context with high recall and relevance.
RAG: Retrieval Re-ranking
Re-rank retrieved docs to keep only the most relevant.
RAG Optimization 1 · Hybrid Search
Keyword + semantic search for higher recall.
RAG Optimization 2 · Re-ranking
Find the most relevant docs before the LLM.
RAG Optimization 4 · Semantic Cache
Stop asking the same question twice.