
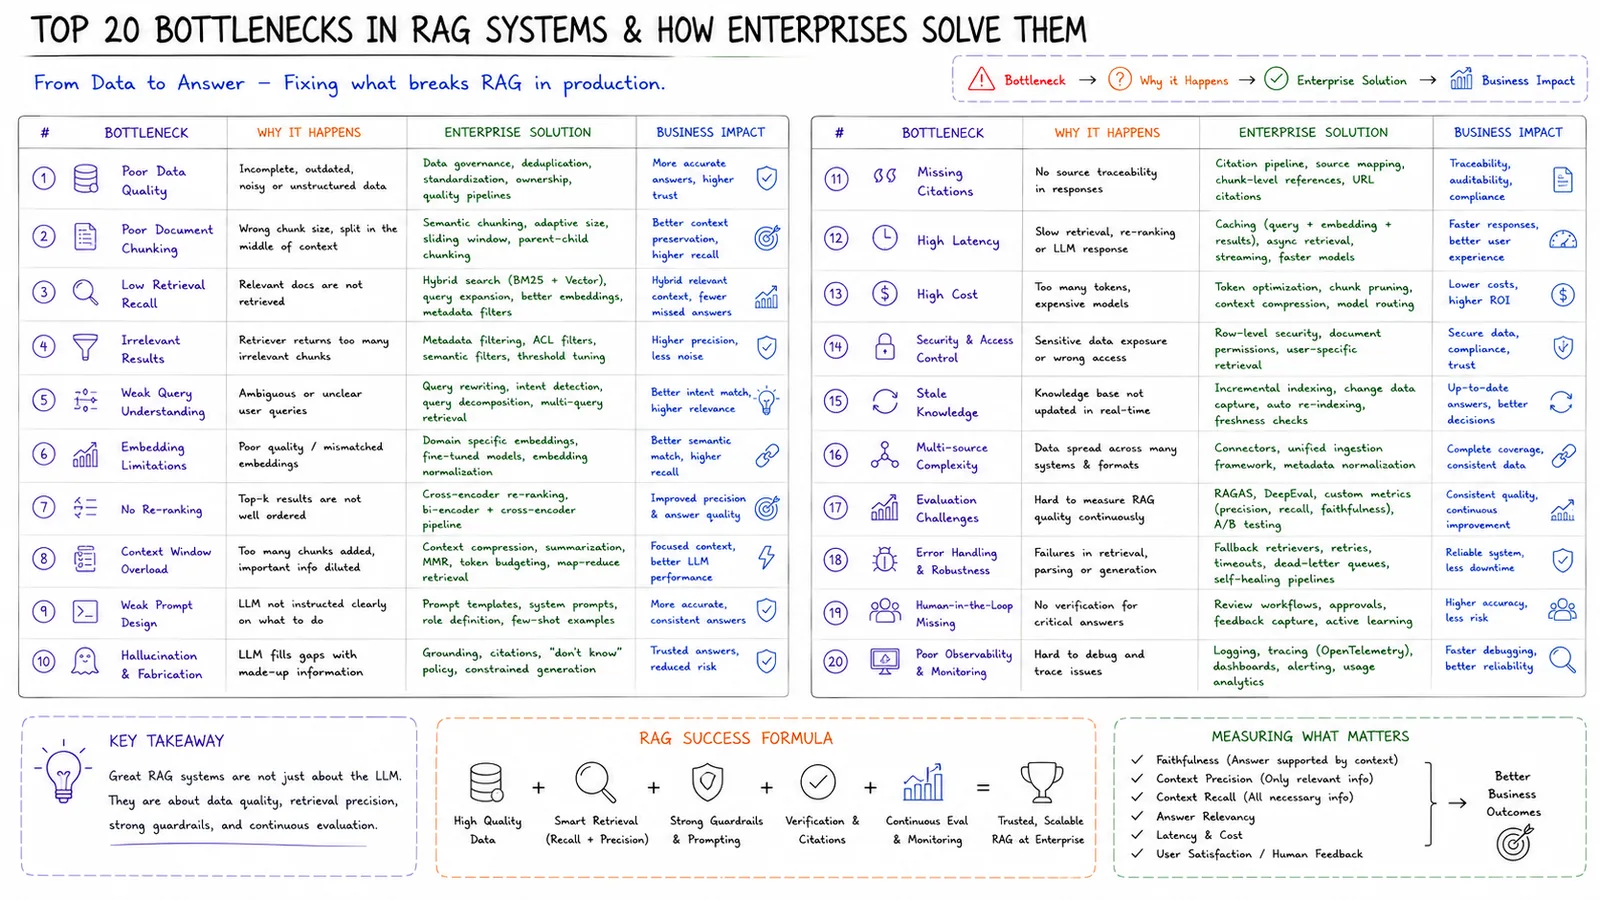
This cheat sheet covers the top 20 bottlenecks in RAG systems and how enterprises solve them — from data to answer, fixing what breaks RAG in production.
In simple terms
The 20 things that break RAG, and the fix for each.
How it works
- 1Poor data quality → data governance, deduplication and cleaning.
- 2Poor document chunking → semantic/adaptive chunking with the right size.
- 3Low retrieval recall → hybrid search (BM25 + vector) and query expansion.
- 4Irrelevant results, weak queries, no re-ranking → metadata filtering, query understanding, cross-encoder reranking.
- 5Context overload, missing citations, high latency/cost → compression, source mapping, caching and reranking.
Key points
- Great RAG isn't just the LLM — it's data quality, retrieval precision, guardrails and evaluation.
- RAG success formula: high-quality data + smart retrieval + grounding + verification + monitoring.
- Measure faithfulness, context precision/recall, answer relevance and latency/cost.
- Continuous evaluation and monitoring keep quality high.
Why it matters
RAG has many failure points beyond the model. This cheat sheet maps each to a fix, so teams build trustworthy, scalable RAG at enterprise scale.
Frequently asked questions
- What's the RAG success formula?
- High-quality data + smart retrieval (recall + precision) + strong grounding + verification + monitoring.
- What breaks RAG most often?
- Data quality and chunking upstream, and weak retrieval/re-ranking downstream.
More in Top 20 Cheat Sheets
Top 20 Bottlenecks in LLMs
From prompt to production — fixing what breaks LLMs.
Top 20 AI Agent Bottlenecks
How enterprises solve agent bottlenecks.
Top 20 Token & Cost Bottlenecks
Optimize token usage and control cost.
Top 20 Python Libraries for AI Engineers
Essential libraries and the problems they solve.