
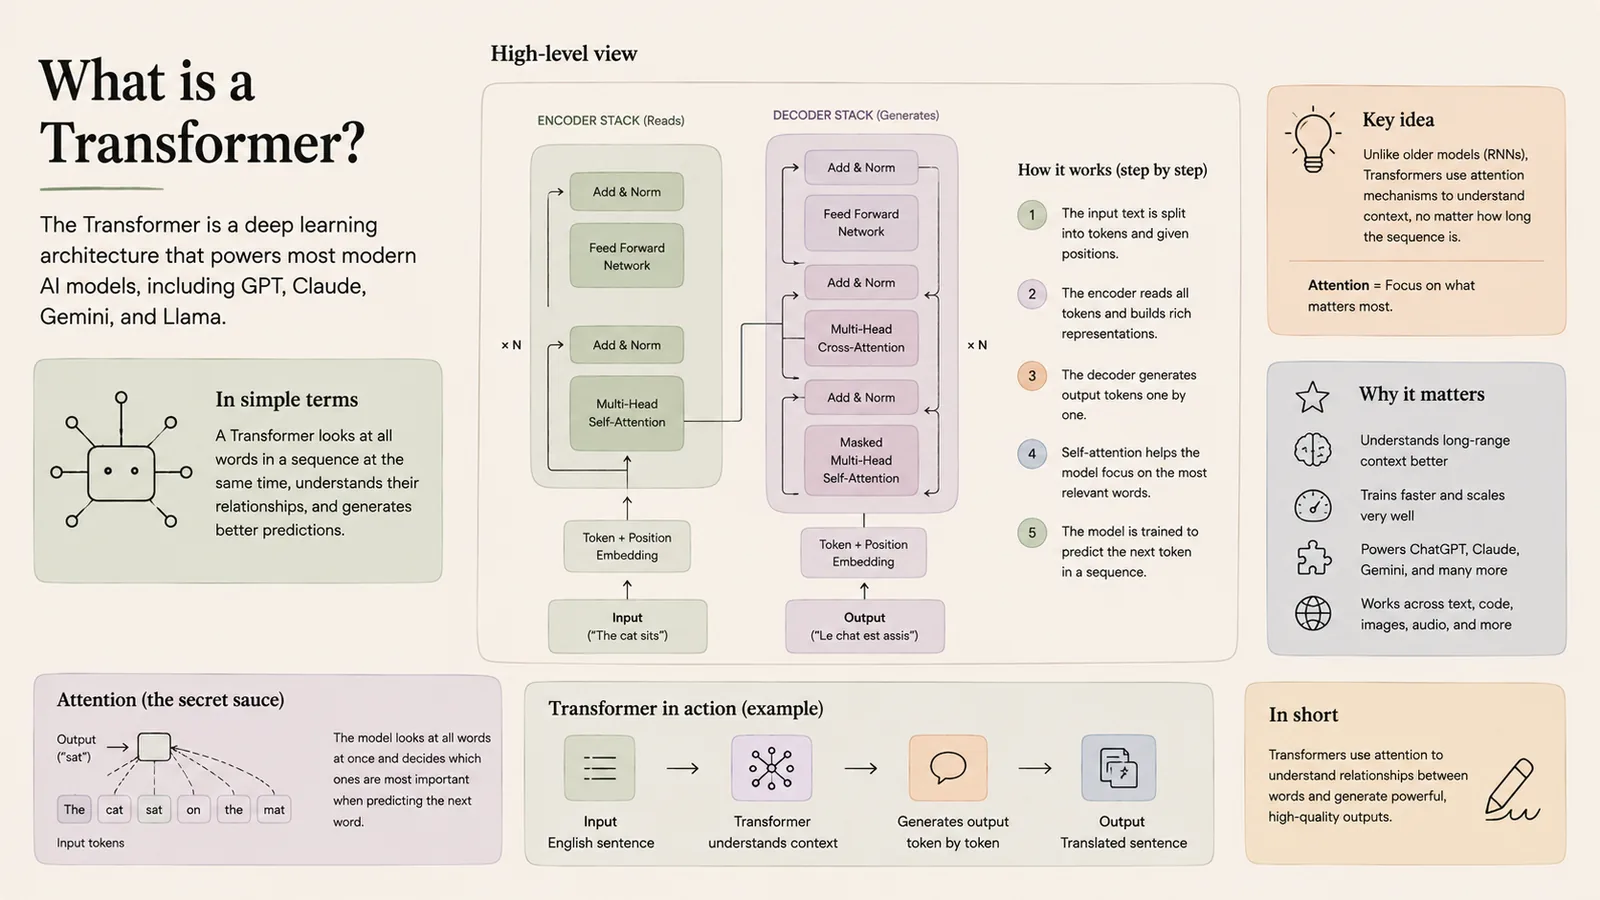
The Transformer is a deep learning architecture that powers most modern AI models, including GPT, Claude, Gemini and Llama. Its key idea is attention: the model looks at all words in a sequence at once and decides which ones matter most for each prediction.
In simple terms
An architecture that uses attention to understand context, no matter how long the sequence is.
How it works
- 1The input text is split into tokens and given positions.
- 2The encoder reads all tokens and builds rich representations.
- 3The decoder generates output tokens one by one.
- 4Self-attention helps the model focus on the most relevant words.
- 5The model is trained to predict the next token in a sequence.
Key points
- Attention = focus on what matters most, across the whole input at once.
- Unlike older RNNs, Transformers handle long-range context and train in parallel, so they scale well.
- An encoder stack reads; a decoder stack generates — GPT-style models use the decoder.
- It works across text, code, images and audio.
Why it matters
The Transformer is the reason today's language models are so capable. Attention lets a model weigh every word against every other word, capturing meaning and context far better than the sequential models that came before.
Frequently asked questions
- What is self-attention?
- A mechanism that lets each token look at all other tokens and decide which are most relevant when producing the next output.
- Why did Transformers replace RNNs?
- They understand long-range context better and process a whole sequence in parallel, making them faster to train and far more scalable.
More in AI Foundations
What is AI (Artificial Intelligence)?
How AI works and its types — narrow, general, super.
What is Machine Learning?
Supervised, unsupervised and reinforcement learning.
What is Deep Learning?
Multi-layer neural networks that learn features.
What is a Neural Network?
Layers of connected neurons that learn patterns.
Inference
Turning a trained model into predictions.
Batch Inference
Process many inputs at once for efficiency.