
Enterprise Hallucination Prevention Pipeline
Verify every answer with layered checks.
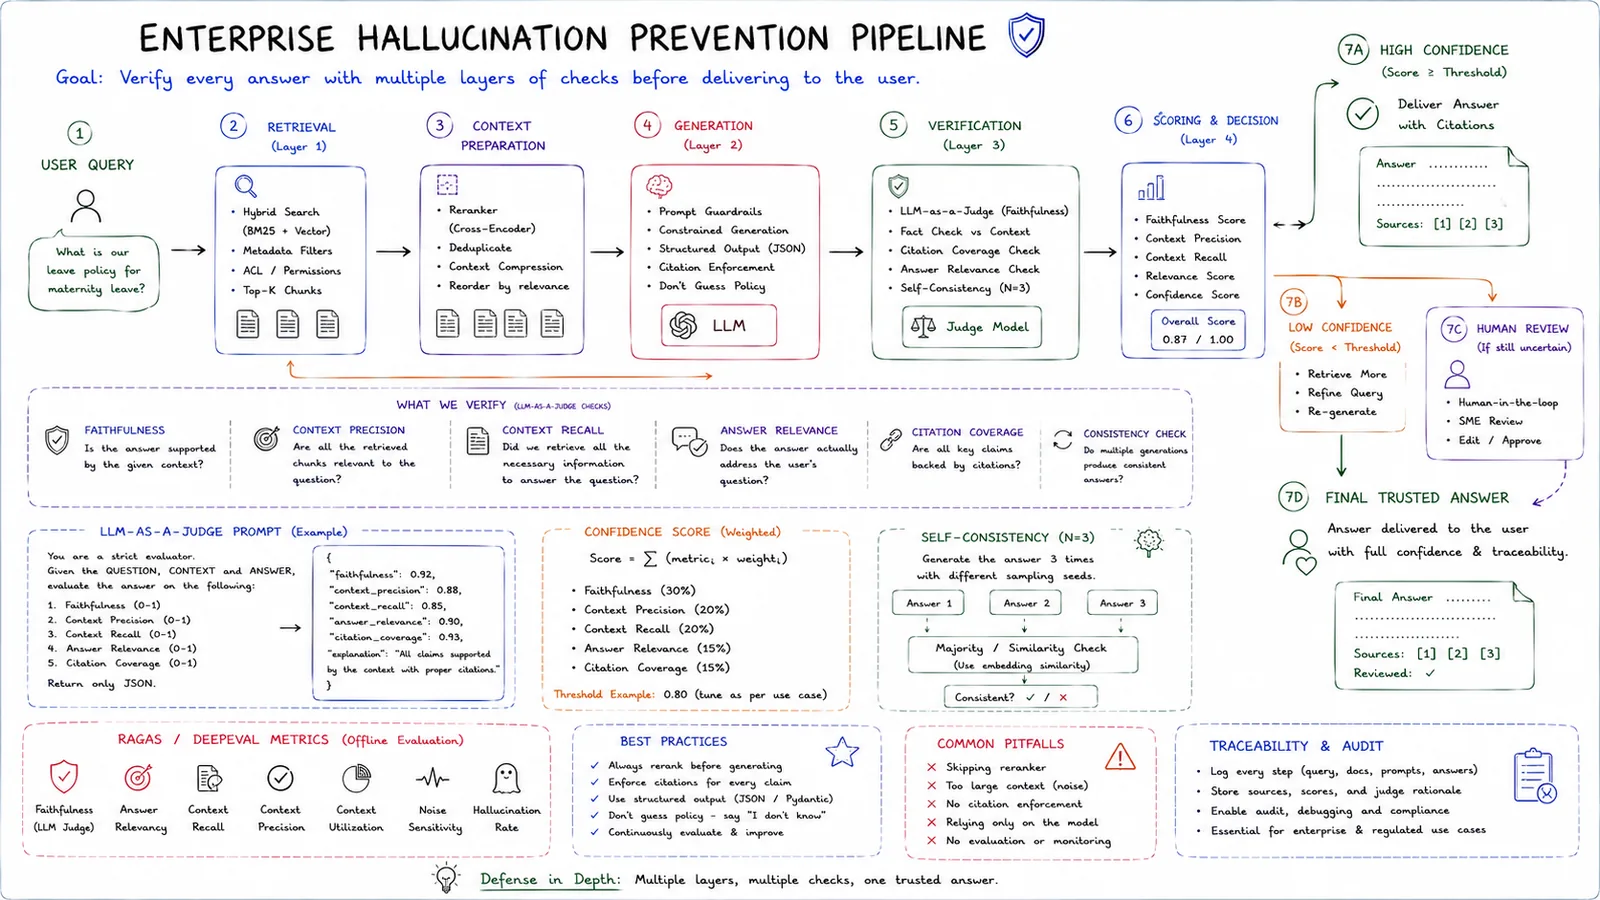
This is an enterprise hallucination prevention pipeline that verifies every answer with multiple layers of checks before delivering it to the user — defense in depth for trustworthy AI.
In simple terms
Layer retrieval, generation, verification and scoring so wrong answers are caught before delivery.
How it works
- 1Retrieval (layer 1): hybrid search, re-ranking, metadata filters and deduplication.
- 2Generation (layer 2): prompt guardrails, constrained generation and structured output.
- 3Verification (layer 3): an LLM-as-a-judge checks faithfulness, context recall and answer relevance.
- 4Scoring & decision (layer 4): compute a confidence score; high confidence delivers with citations.
- 5Low confidence triggers retrieval refinement or human review before a final trusted answer.
Key points
- Verify faithfulness, context precision/recall, answer relevance, citation coverage and consistency.
- Self-consistency (N samples) checks agreement across attempts.
- Use offline metrics (RAGAS, DeepEval) plus online monitoring.
- Defense in depth: multiple layers, multiple checks, one trusted answer.
Why it matters
For regulated or high-stakes enterprise use, one guardrail isn't enough. Layered verification catches errors before they reach users, enabling trustworthy AI.
Frequently asked questions
- What is LLM-as-a-judge?
- Using a model to evaluate an answer's faithfulness, relevance and citation coverage against the context.
- What happens on low confidence?
- The pipeline refines retrieval, regenerates, or routes to a human before delivering an answer.
More in RAG & Retrieval (Enterprise)
Where Hallucinations Come From
Failures across the query, retrieval and model layers.
RAG Retrieval Optimization Layer
Retrieve the right context with high recall and relevance.
RAG: Retrieval Re-ranking
Re-rank retrieved docs to keep only the most relevant.
RAG Optimization 1 · Hybrid Search
Keyword + semantic search for higher recall.
RAG Optimization 2 · Re-ranking
Find the most relevant docs before the LLM.
RAG Optimization 3 · Context Pruning
Remove noise; keep only what matters.